Flagship · Batch ELT
Retail data platform on AWS
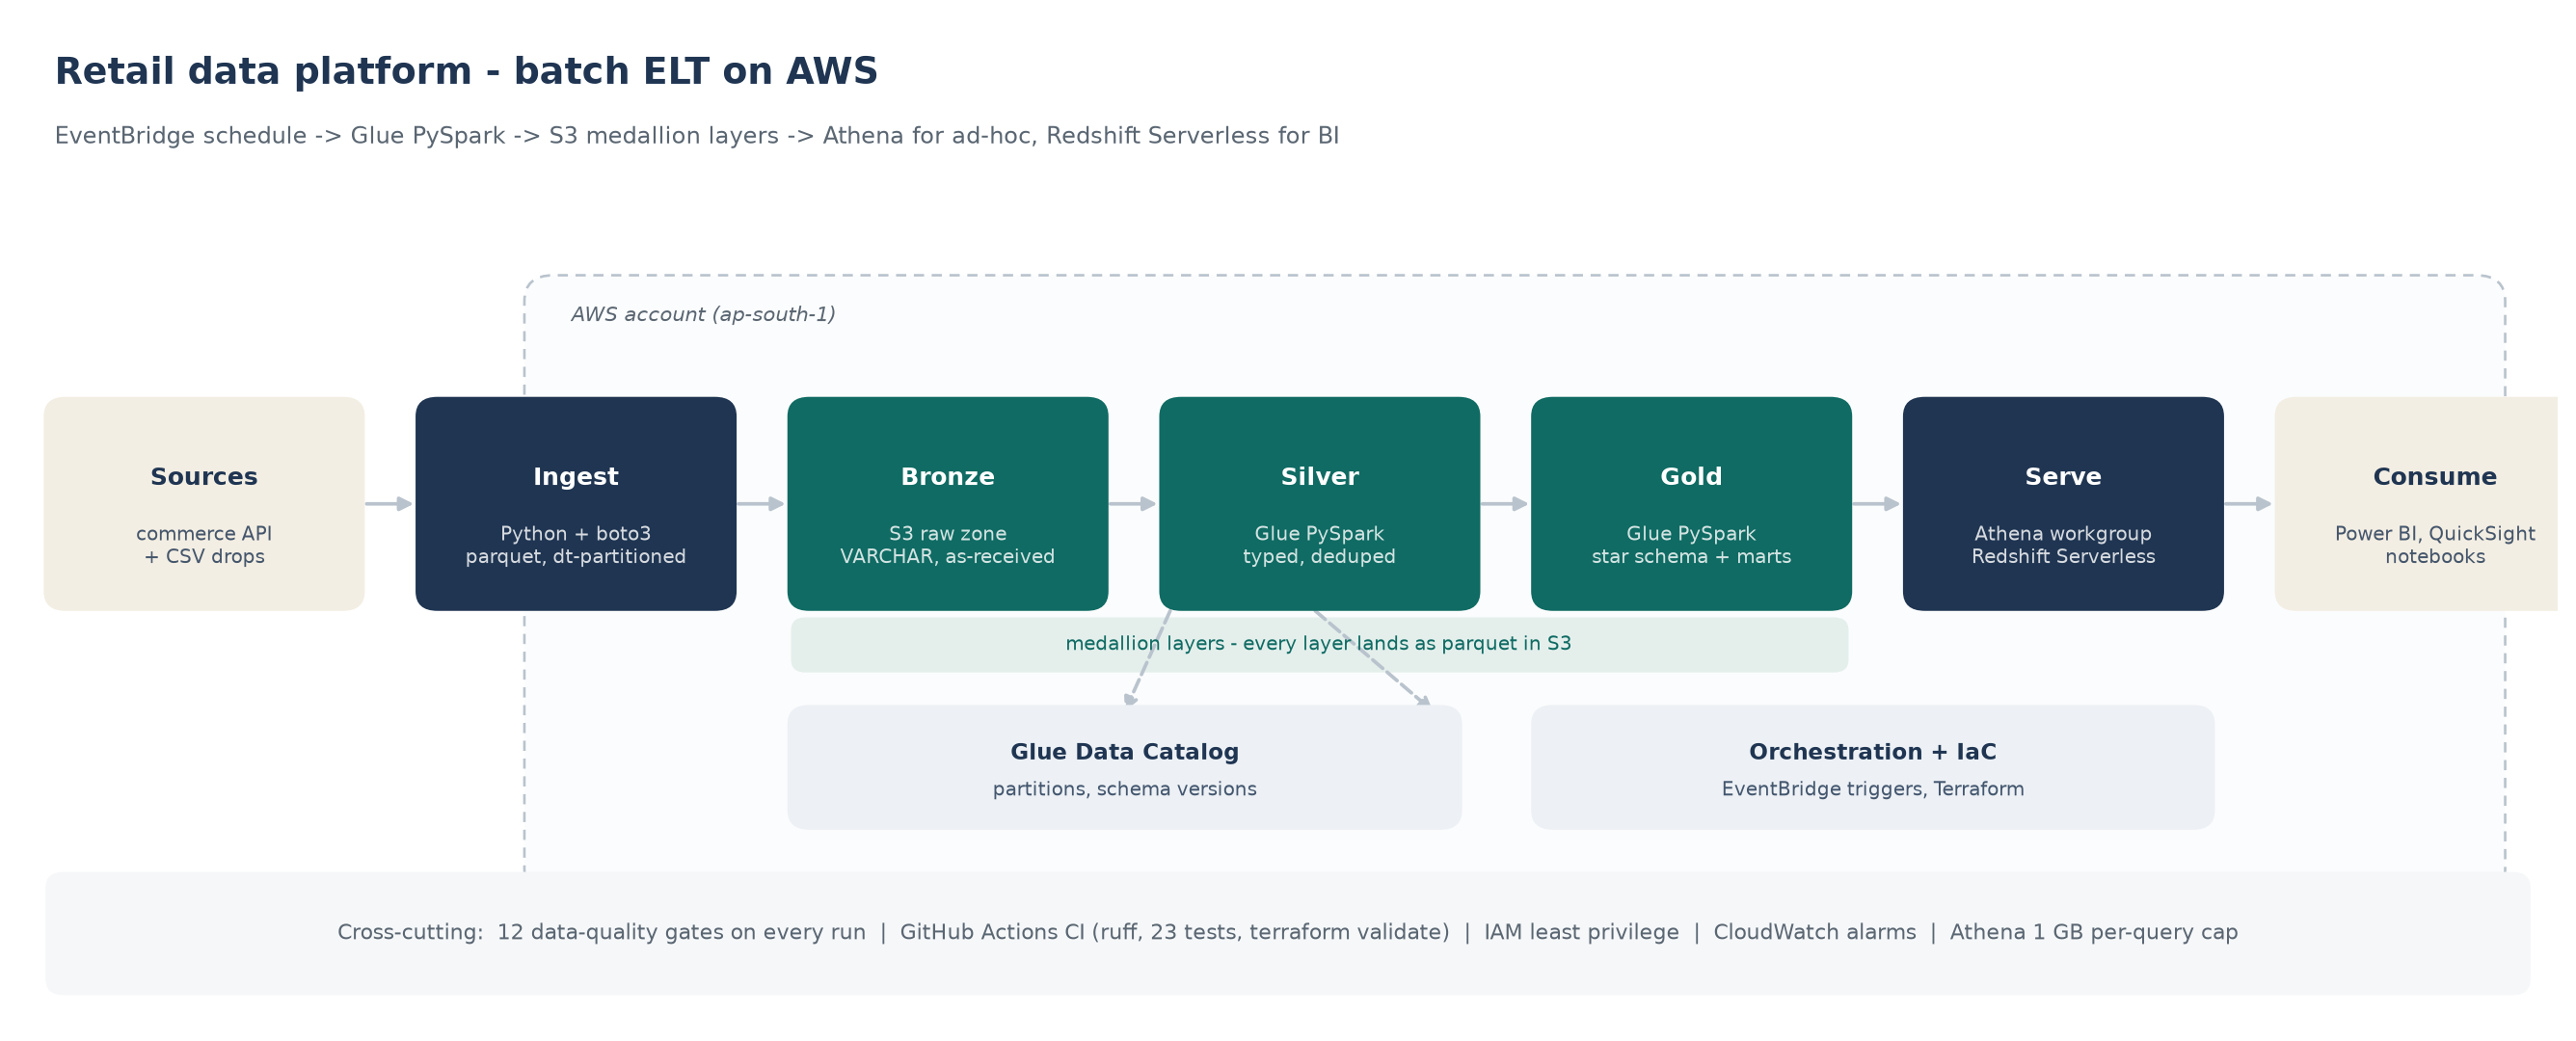
Four inconsistent CSV exports land in S3, get cleaned once in Glue, and come out as a tested star schema that Athena and Redshift can both read. A run that fails a quality gate publishes nothing.
Data Engineer · Bangalore, India
I build pipelines that land messy data, test it, and refuse to publish a number that fails a check — batch on AWS, streaming with Kafka and Spark, and dbt on top.
Open to data engineering roles · Bangalore or remoteTest count is current as of the last run on each repository: 23 + 27 + 20 + 5. CI status below is live, not a screenshot — each badge links to that repo's Actions page.
Selected work
Three of the four run offline from a clean clone in under a minute — I ran each one to produce the numbers below. The fourth needs a public dataset download, and an AWS account for its cloud path. Every project carries its own test suite and states in its README exactly what it does not do.
About the numbers: the datasets behind every figure on this page are synthetic or public sample data, generated to reproduce the defects real exports have. The pipelines, the tests, the CI and the infrastructure are real and reproducible — the revenue is not a real company's. Each README says which parts run in CI and which need Docker or an AWS account.
Flagship · Batch ELT
Four inconsistent CSV exports land in S3, get cleaned once in Glue, and come out as a tested star schema that Athena and Redshift can both read. A run that fails a quality gate publishes nothing.
Streaming
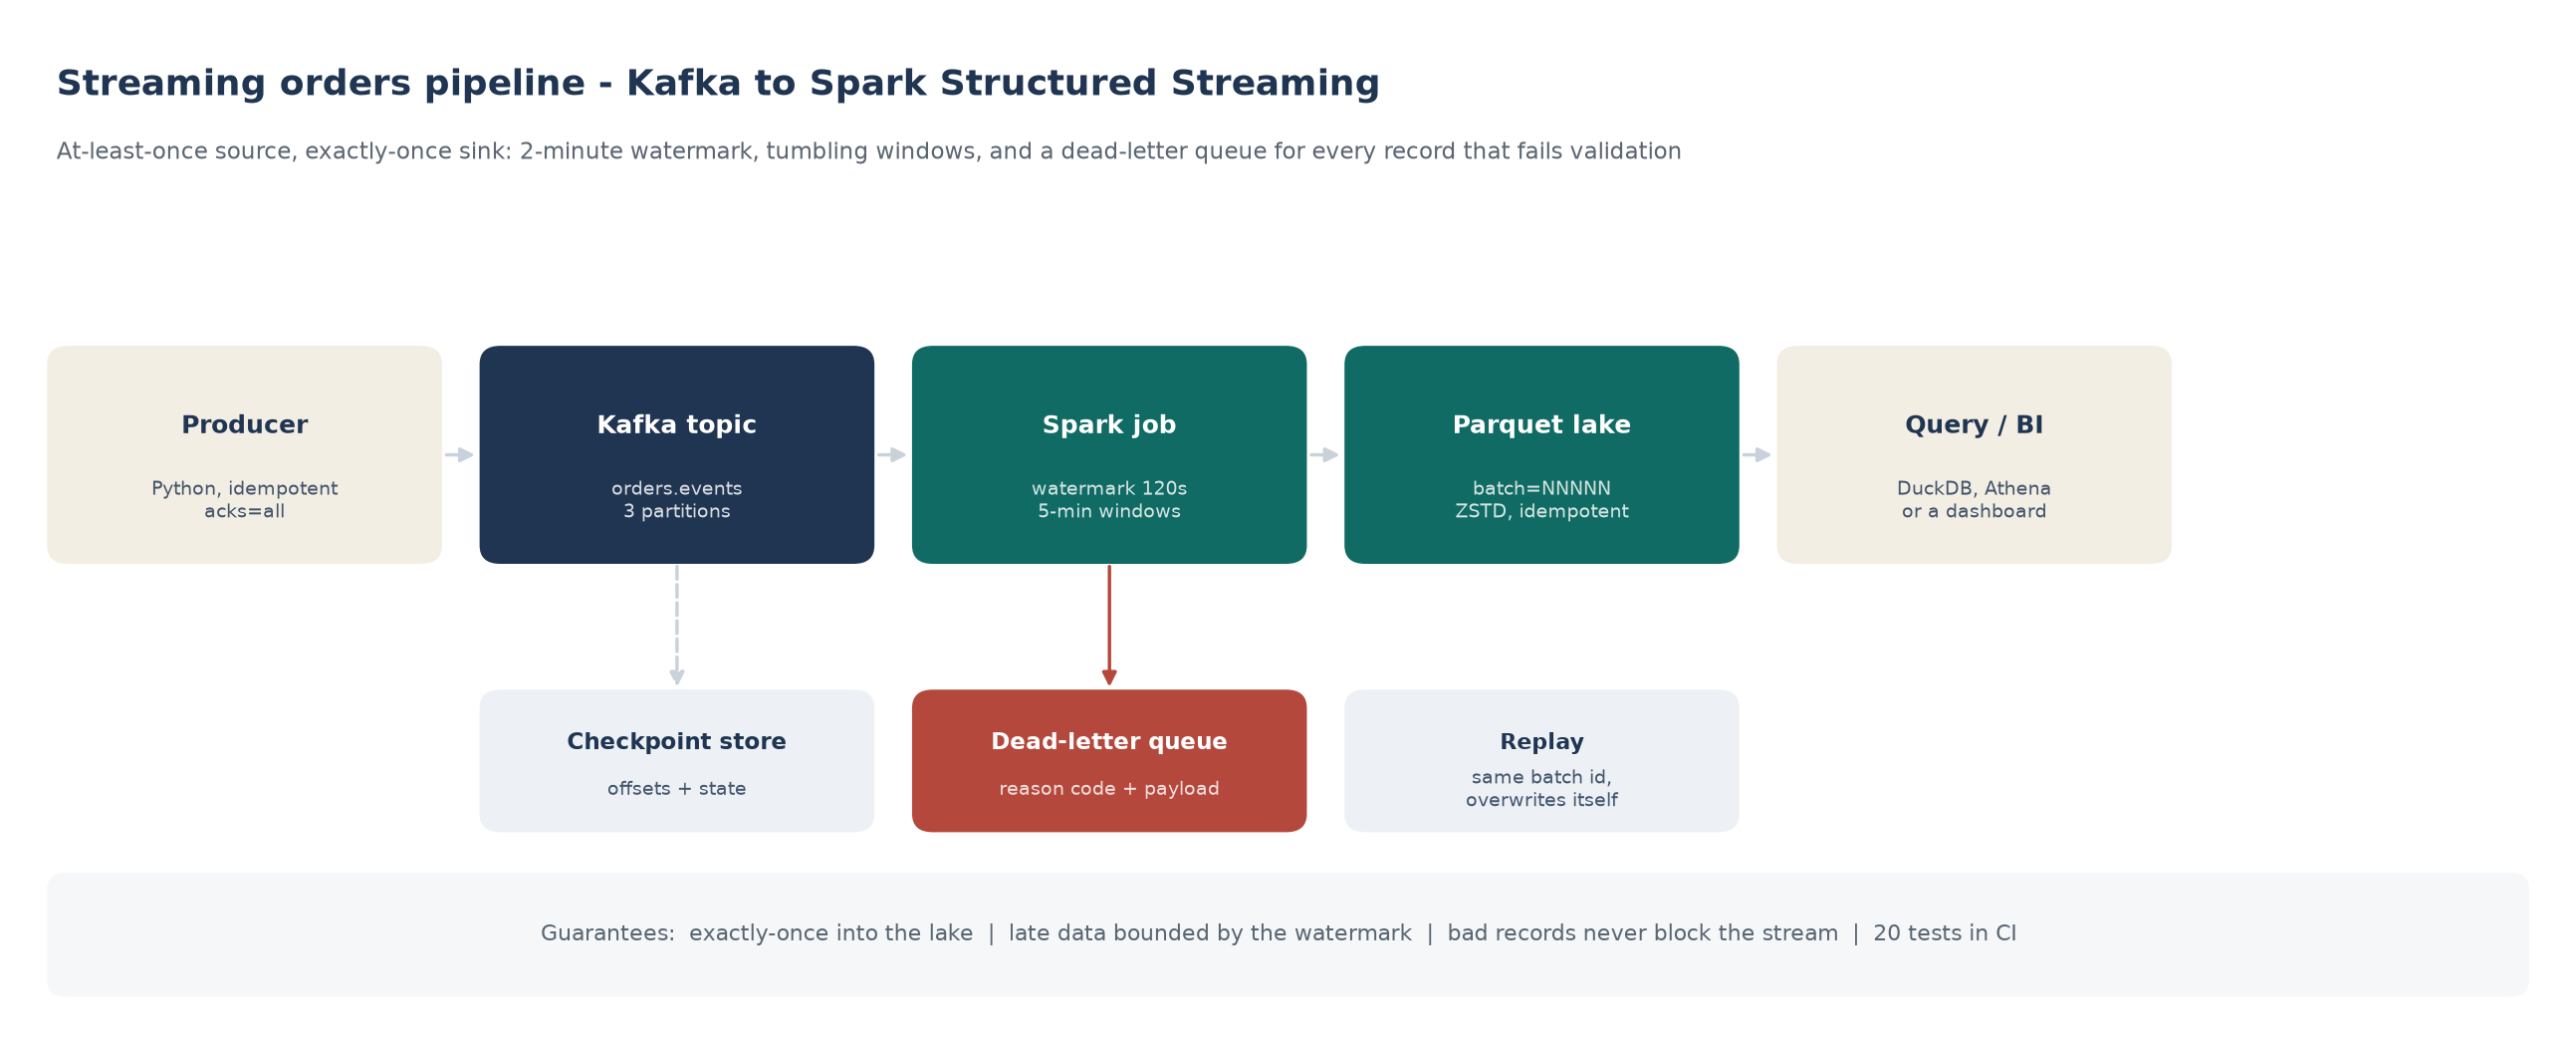
At-least-once delivery, out-of-order mobile clients and poison records handled explicitly: dedupe, a 120-second watermark, and a dead-letter queue that explains every rejection.
Analytics engineering
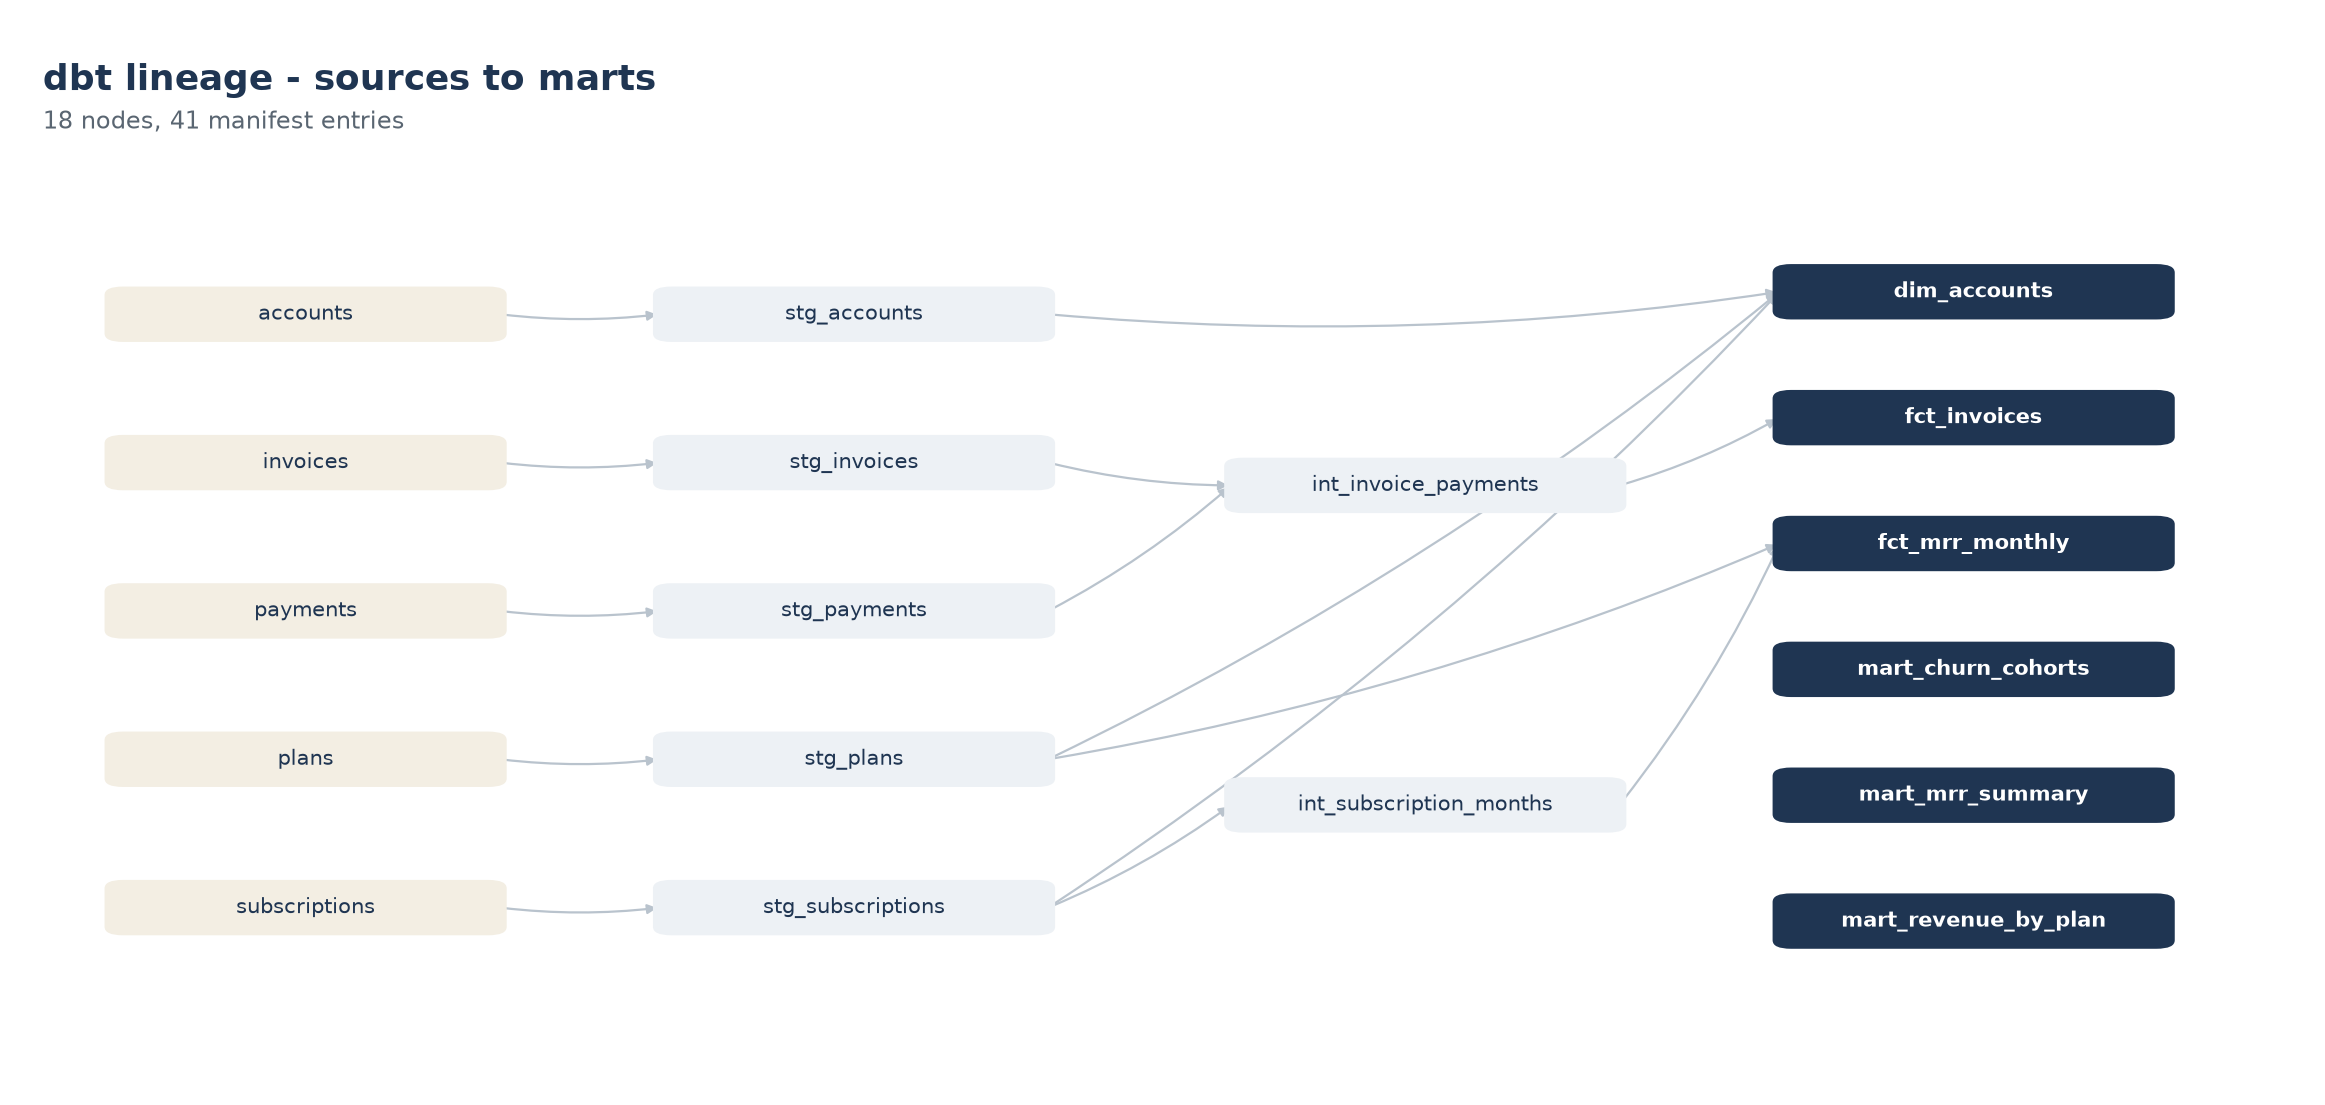
MRR, net new MRR and cohort retention defined once, in one model, so the numbers reconcile by construction. Incremental fact table, a type-2 snapshot, 27 tests.
Lakehouse
A bronze / silver / gold lakehouse over the public NYC TLC trip records: Glue transformations, Athena analysis, and Terraform for every bucket and job. The project where the AWS patterns started.
Stack
Only what the four repositories above can back up. Nothing listed here is something I have read about but never shipped.
Languages
Python — pipelines, tests, toolingSQL — modelling, window functionsPySpark — batch and streaming jobsData
dbt — models, tests, snapshotsKafka — topics, offsets, delivery semanticsParquet — partitioning, compressionDuckDB — local warehouse, fast iterationCloud
S3 — medallion layers, lifecycle rulesGlue — catalog, crawlers, ETL jobsAthena — external tables, partition pruningRedshift Serverless — COPY, MERGE, dist/sort keysEngineering
Terraform — every bucket, Glue job, workgroup and alarm in the AWS platformpytest — unit and contract testsGitHub Actions — CI on every pushDocker — local Kafka stackEducation
Bachelor of Technology — Computer Science (Artificial Intelligence & Machine Learning)
Contact
I am looking for a first data engineering role in Bangalore, or remote. The fastest way to
judge whether I can do the work is to run one pipeline yourself. For the flagship:
git clone https://github.com/Yashu24-coder/aws-retail-data-platform && cd aws-retail-data-platform && make run
— about ten seconds, no AWS account, no Docker. The
README
documents the same steps, and every project has its own Quickstart.